
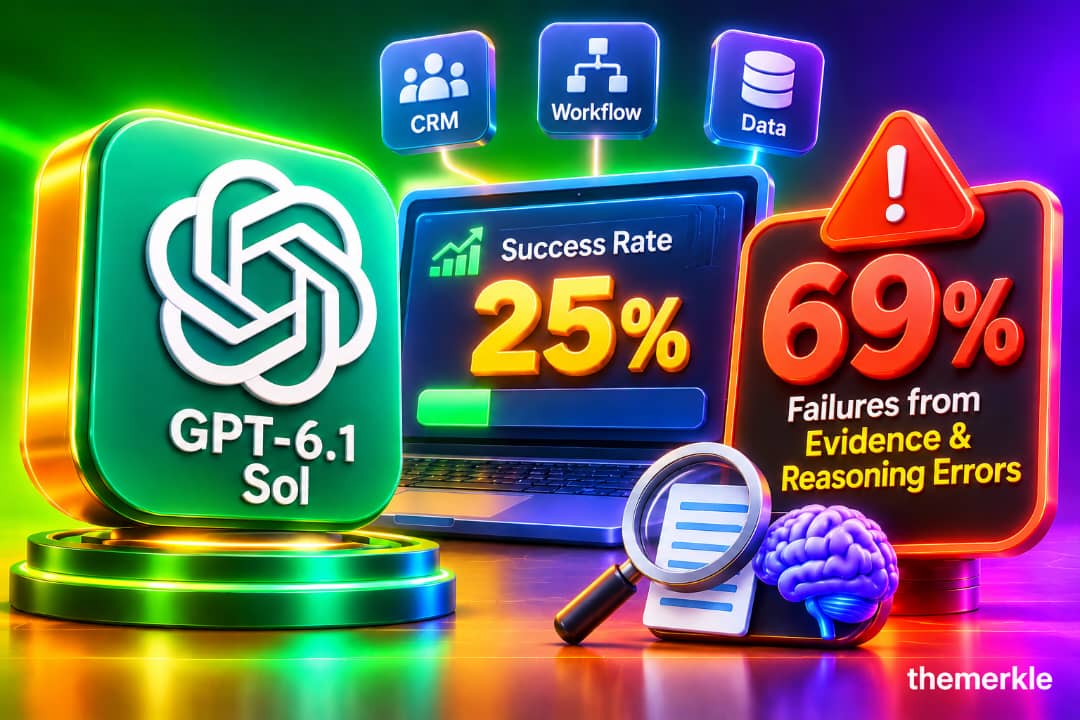
Collinear’s FrontierCUA benchmark tests 20 computer-use agents on 40 held-out enterprise workflows. GPT-6.1 Sol leads at 25%, and 69% of its lost points come from evidence gathering and reasoning.
The best computer-use agent on a new enterprise benchmark rarely misses because it clicked the wrong button. It misses because it didn’t look at everything first.
A Benchmark Built Around Enterprise Operations
Collinear AI released FrontierCUA on November 6. It is a private set of 40 enterprise workflows, each run on functional clones of real software. Collinear built the clones itself, reproducing the interfaces of products including Zendesk, Shopify, HubSpot, GitHub, Jira, Cloudflare, Datadog, Notion and Google Workspace. The tasks span 11 enterprise functions and 30 applications, with customer support and site reliability engineering leading. Every workflow touches at least two apps, and 16 of the 40 reach four or five.
Collinear’s pitch is that earlier benchmarks covered the wrong work. OSWorld and its successors focus on personal-assistant tasks, and Agent’s Last Exam targets specialist desktop software. Enterprise operations, the high-volume jobs that keep a business running, were largely uncovered. The best model, GPT-6.1 Sol, passes 25% of them, and across the 20 models tested, 23 of the 40 tasks were solved by none.
How FrontierCUA Builds and Grades a Task
The instructions are short, with a median of about 70 words, but the work behind them is long. A typical run takes around 374 steps and 36 minutes, under a cap of two to three hours. Agents work only from screenshots and mouse or keyboard actions. They get no source code for the clones, no API and no database, and tasks forbid dev tools, export URLs and code.
An agentic judge grades the final state of each app against atomic yes-or-no rubric checks, weighted by importance, because correct answers can be written in many valid ways and live in application state. The judge also reads the rollout to resolve intent, which helps stop agents from gaming completion evidence. A pass requires a reward of 0.95 or higher.
Quality checks cover four parts of each task: the instruction, the rubric, the seeded world and the rollout. On top of that, every task ships with a reference solution that scores 1.0, so each one is solvable as written.
What the Leaderboard Shows
The live FrontierCUA leaderboard reports three figures per model: pass@1, avg@1 and cost. All the entries on screen as of November 9 ran at the high reasoning setting. Because there are 40 tasks, each one is worth 2.5 percentage points, so GPT-6.1 Sol’s 25.0% means 10 passes. Muse Wonder’s 12.8% is the exception. The metric is the fraction of a model’s graded tasks that pass, which suggests 5 of 39.
GPT-6.1 Sol leads on both pass rate and average reward, with an avg@1 of 0.495 and a cost of $6.00. GPT-6 Astra is second at 20.0%, then Opus 5 at 17.5%. Fable 5.1 and Fable 5 tie at 15.0%. Muse Wonder follows at 12.8%, and four models share 12.5%: Opus 5.5, Kimi K3, Sonnet 5 and MiMo V2.6 Flash.
 Below that, the board thins quickly. GPT-6 Sol, GPT-6.1 Terra, Grok 4.7 and GPT-5.6 Sol sit at 7.5%, MiMo V2.6 Pro at 5.0%, and Kimi K3.1 Pro, GLM 5.3 FlashX and DeepSeek V4.1 Flash at 2.5%. Qwen 3.8 Max appears at 0.0% in the partly visible next row.
Three details stand out. First, the gaps are tiny in task terms. The leader’s edge over GPT-6 Astra is two tasks, and the four-way tie at 12.5% is five tasks each, so rank order among the middle entries means little.
Second, avg@1 tells a different story from pass@1. Fable 5.1 ranks fourth on passes but second on average reward at 0.453, and Opus 5.5 posts a higher average (0.442) than Opus 5 (0.431) despite passing fewer tasks. Partial progress and full completion are not the same skill.
Third, cost varies wildly. GPT-6 Astra’s $47.94 is nearly eight times the leader’s price for a lower score, while Muse Wonder costs $55.23 and Grok 4.7 $71.96 for 7.5%. At the other end, MiMo V2.6 Flash matches Sonnet 5 and Kimi K3 at 12.5% for $1.31.
Why 69% of Failures Are About Thinking, Not Clicking
The most interesting result is the failure breakdown. Collinear classified the lost rubric points on all 40 of GPT-6.1 Sol’s runs into five causes, using a model to read each rollout and the judge’s reasoning. Evidence gathering accounts for 39%: the agent acts before collecting the facts a decision rests on, stops searching early or never opens a needed source. Reasoning over evidence adds 30%: the agent has the right information and draws the wrong conclusion. Together, that makes 69%.
Stopping before finishing explains another 24%, where the agent declares itself done with most of its budget unused. Interface errors, including grounding mistakes like clicking the wrong element, account for only 5%, and arithmetic slips for 2%. On the 10 newest tasks, reasoning over evidence rises to 45%.
Collinear’s worked example shows what that looks like. In a CRM task, an agent must route 44 inbound sales leads in HubSpot using rules in Slack and records in Zendesk and Notion. Two leads give different business names but share one USDOT number, a federal identifier that stays fixed when a carrier rebrands, so they are one account. The agent, Claude Opus 5.5 in this case study, opened every page it needed and never connected the shared number. That was a reasoning miss, not a navigation miss.
For years, computer-use progress was framed around grounding, meaning finding and clicking the right pixel. On this benchmark, that problem is largely solved. The bottleneck has moved from hands to judgment.
What the 25% Pass Rate Does and Doesn’t Tell Buyers
The headline number needs careful reading. A reward threshold of 0.95 gives no credit for a mostly correct workflow. The 40 tasks are held out and private, which protects against training contamination but means outsiders can’t rerun them, and the clones are Collinear’s own. Collinear also sells evaluation and reinforcement-learning environments, so independent replication will matter.
The harnesses differ by provider as well. Anthropic models use their native computer-use tool, OpenAI models use the Codex agent through a desktop CLI, and open models use the OSWorld pyautogui agent. That complicates comparisons. Kimi K3 passes 12.5% while the newer Kimi K3.1 Pro passes 2.5%, and a generic open-model harness could be part of the reason, though the benchmark can’t confirm it.
Cost per success offers a sharper lens. Dividing each rollout’s cost by its pass rate, and ignoring retries, gives about $24 per pass for GPT-6.1 Sol, roughly $240 for GPT-6 Astra, and around $10 to $12 for MiMo V2.6 Flash and GPT-6.1 Terra. These are rough estimates from the leaderboard’s figures, not numbers Collinear reports. They suggest the cheapest competent agent may beat the most capable one on economics, even though the leader is still best on pass rate.
What to Watch as the Benchmark Grows
Collinear says it will add more tasks in existing domains, along with longer workflows in MLOps, data engineering, IT and security operations and finance operations. As the set grows, each task will count for less, which should make rankings steadier.
The lesson here isn’t the 25%. It is where the failures cluster. If two-thirds of lost points come from missing evidence or misreading it, better clicking won’t fix enterprise agents. They need habits that look like diligence: exhaust the sources, cross-check identifiers and never declare victory early. Teams evaluating agents for support, sales operations or IT work should test for those behaviors on their own data before trusting a leaderboard number.
Disclosure: This is not trading or investment advice. Always do your research before buying any cryptocurrency or investing in any services.
Follow us on Twitter @themerklehash to stay updated with the latest Crypto, NFT, AI, Cybersecurity, and Metaverse news!